How to Production-Test an Edge AI Product

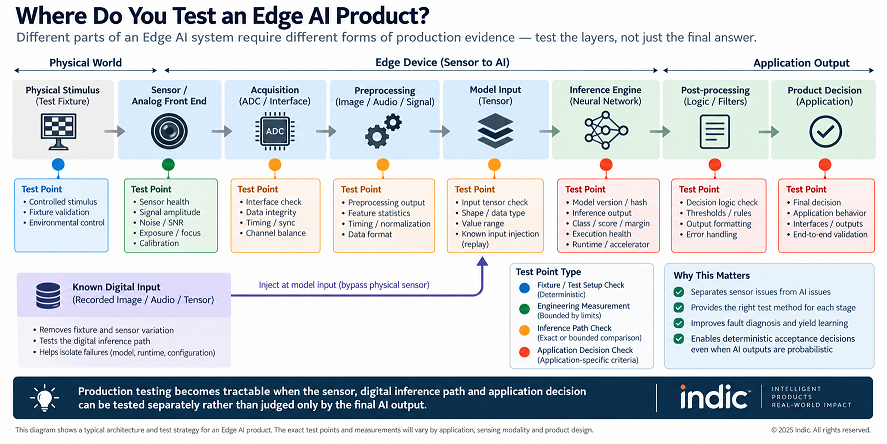
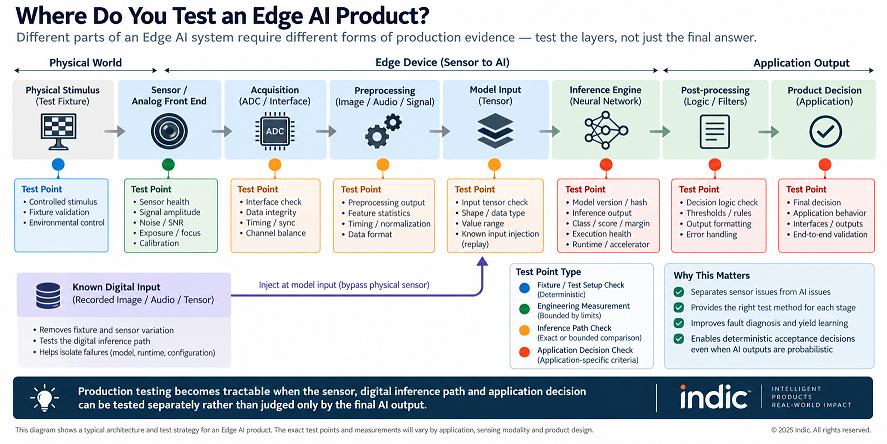
Diagram of an Edge AI production-test architecture from controlled physical stimulus through sensor, acquisition, preprocessing, model input, inference, post-processing and product decision. Test points are classified as deterministic fixture checks, bounded engineering measurements, inference-path checks or application-decision checks, with a known digital replay path shown as an example diagnostic injection point.

How Do You Production-Test an Edge AI Product When the Output Is Probabilistic?

A practical framework for deterministic checks, sensor-path measurements, inference acceptance criteria and statistical process monitoring.

A conventional electronic product lends itself to a familiar production-test question: Did the unit produce the expected output when given a known input? Measure a voltage. Read a register. Exercise an interface. Inject a signal. Compare the result with a limit. Pass or fail.

An Edge AI product complicates that logic. A vision system may report defect: 0.91 on one unit and defect: 0.88 on another. An acoustic classifier may identify the same event on every unit while assigning slightly different scores. An anomaly detector may return a continuously varying value rather than a clean binary result.

So what should an end-of-line tester actually accept?

An Edge AI product does not require every internal inference value to be identical. It requires a production acceptance architecture that makes the conformity decision explicit, repeatable and diagnosable.

That means separating what should match exactly, what should remain inside engineering limits, what requires model-specific acceptance criteria, and what is more useful as a statistical process indicator. The manufacturing decision can be deterministic even when some of the evidence feeding that decision is not a single fixed number.

Probabilistic Does Not Necessarily Mean Random

The word probabilistic can create unnecessary confusion.

A classifier may produce scores that resemble probabilities, but that does not mean the inference engine is randomly generating a different answer each time. With a fixed input, model, runtime and hardware environment, many inference pipelines can be configured for deterministic execution. PyTorch's reproducibility guidance explicitly distinguishes deterministic execution on a controlled platform from reproducibility across releases and platforms; TensorFlow's deterministic-operations guidance makes the same distinction for supported operations.

That computational question is different from the variation introduced by the physical product. A camera observing the same target does not necessarily produce an identical pixel array on every acquisition. Illumination changes slightly. Sensor noise changes. Focus and alignment vary. Analog front ends have tolerances. Microphones, radar front ends, accelerometers and other sensing systems introduce their own forms of physical variation.

Those changes can propagate through preprocessing and into model outputs. For production test, it is therefore useful to distinguish three sources of variation:

  • Measurement variation, introduced by the fixture, stimulus and measurement system.
  • Product variation, introduced by sensors, optics, analog electronics, mechanics, calibration and assembly.
  • Inference variation, where changes in the input representation move the model output within its decision space.

Calling all three “AI uncertainty” makes fault isolation harder.

What Is Production Test Actually Trying to Prove?

A factory test does not need to prove that the AI model generalizes to every possible field condition. That belongs to engineering validation.

Given a validated product design and a controlled production stimulus, does this manufactured unit remain inside the accepted hardware, sensor, configuration and intelligent-function envelope?

Model validation may require representative datasets, difficult operating conditions, environmental corners, robustness evaluation and application-performance metrics. Production test should extract from that validation work a smaller, controlled set of tests capable of detecting whether an individual manufactured unit still conforms to the validated design. NIST AI RMF measurement guidance similarly emphasizes documented test sets, metrics, repeatable TEVV and monitoring of AI-system behavior in production.

The production line is one part of the evidence chain. It is not a substitute for model or product validation.

Test the Layers, Not Just the Final Answer

A useful Edge AI production-test architecture separates four test layers.

Test layer Engineering question Appropriate acceptance logic
Hardware and configuration Is the unit assembled, provisioned and configured correctly? Exact / hard pass-fail
Sensor and signal path Is the physical input reaching the AI pipeline within specification? Bounded engineering limits
Inference path Does a controlled input produce acceptable model behavior? Exact, bounded or model-specific comparison
Product decision Does the system perform the required application function? Application-specific acceptance criteria

Diagram of an Edge AI production-test architecture from controlled physical stimulus through sensor, acquisition, preprocessing, model input, inference, post-processing and product decision. Test points are classified as deterministic fixture checks, bounded engineering measurements, inference-path checks or application-decision checks, with a known digital replay path shown as an example diagnostic injection point.
Production testing becomes tractable when the sensor, digital inference path and application decision can be tested separately rather than judged only by the final AI output.

The important point is that these layers should not all be inferred from one final model output. A marginal camera may still classify today’s test target correctly. A slightly misaligned optical assembly may still provide enough information for the expected class. An acoustic input stage with excessive gain variation may still recognize a loud fixture stimulus.

If production records only “PASS — model returned the expected class,” potentially useful information about the condition of the unit disappears. The product has passed the AI decision while the underlying engineering state may already be moving away from nominal.

1. Make Everything Deterministic That Can Be Deterministic

The presence of AI should not weaken conventional production-test discipline. Many characteristics remain straightforward known-answer checks:

  • Supply rails and current behavior
  • Processor and memory identification
  • Sensor communications
  • Storage integrity
  • Firmware and bootloader identity
  • Model identifier or cryptographic hash
  • Runtime configuration
  • Accelerator availability
  • Peripheral interfaces
  • Calibration-record presence and integrity
  • Serial number and provisioning state

These characteristics deserve direct tests. If calibration data is missing, test for missing calibration data. If the wrong model has been loaded, check the deployed model identity. If the sensor interface is faulty, verify the interface rather than relying on a downstream neural network to happen to expose the defect.

This principle improves diagnosis because the model is not being used as an indirect measuring instrument for conditions that can be observed directly.

2. Test the Sensor and Signal Path as an Engineering System

The physical stimulus should enter where the real-world signal normally enters. For a vision product, that might be a controlled optical target and illumination source. For an acoustic product, it could be a calibrated sound stimulus. A radar product may use an appropriate target or simulator. An inertial product may require known orientation or controlled movement.

The important question is not simply: “Did the model recognize it?” The production tester should also capture observables upstream of inference.

  • Signal amplitude
  • Sensor offsets
  • Noise or signal-to-noise measures
  • Image sharpness or another validated image-quality metric
  • Exposure behavior
  • Channel balance
  • Synchronization error
  • Clipping or saturation
  • Calibration residuals
  • Preprocessing statistics

Which measurements belong in production test depends on the product. The general rule is more important: do not use the neural network as the only measuring instrument for the hardware feeding the neural network. A model may tolerate upstream degradation until the input approaches a decision boundary. Manufacturing engineering often needs visibility before that point.

3. Create a Known-Input Test Inside the Digital Inference Path

Where the architecture permits it, one of the most useful diagnostic capabilities is a controlled digital replay test. Instead of presenting a real physical stimulus, inject a known digital artifact somewhere downstream of the physical sensor.

Recorded image / waveform / digital sensor data / feature representation / tensor → preprocessing or model input → runtime → inference → output

The exact injection point is architecture-dependent. The goal is to remove some combination of physical fixture variability, illumination or acoustic coupling, sensor noise, optics or mechanical positioning, and analog-front-end variation so the downstream digital execution chain can be tested more directly.

If a known digital input fails to produce the validated result, investigating lens focus first is unlikely to be productive. If the same digital replay passes while the controlled physical-stimulus test fails, the fault domain shifts upstream toward the sensor, analog path, mechanical alignment, calibration or fixture.

The value of replay testing is therefore not merely repeatability. It creates a diagnostic boundary.

A practical fault-isolation sequence

  1. Configuration check fails → investigate provisioning, hardware identification, firmware, model or calibration state.
  2. Configuration passes; digital replay fails → investigate preprocessing, runtime, accelerator execution, model deployment or digital data path.
  3. Digital replay passes; physical stimulus fails → investigate sensor, analog front end, optics/mechanics, calibration or fixture.
  4. Both paths pass; application decision fails → investigate post-processing, decision logic, thresholds or system-level behavior.

This sequence is an engineering synthesis, not an industry-mandated test standard. Its usefulness depends on whether the product architecture exposes the required injection and observation points.

4. Evaluate the Product Decision With Criteria Appropriate to the Model

Suppose three production units observe the same controlled reference object:

Unit Top prediction Reported score
A Acceptable part 0.96
B Acceptable part 0.93
C Acceptable part 0.89

Should Unit C fail? Those three numbers alone do not provide enough information.

A confidence-like output is not automatically a calibrated probability that the prediction is correct. Research on neural-network confidence calibration has shown that classification confidence can be poorly calibrated even when classification accuracy is strong. A convenient value such as 0.90 therefore does not become a manufacturing specification simply because the model emits a number between zero and one.

The acceptance rule must come from the validated behavior of the model within the product and application.

Inference task Potential production observables
Classification Expected class; validated score rule; first-vs-second margin; output-vector region; controlled repeatability
Object detection Expected object count; class; localization tolerance; application-validated confidence criteria
Regression Allowable error band; bias or offset; repeatability
Anomaly detection Acceptable score region; distance from validated reference population; repeatability or trend behavior

There is no single universal “AI production-test threshold.”

Decision Margin Can Reveal What the Winning Class Hides

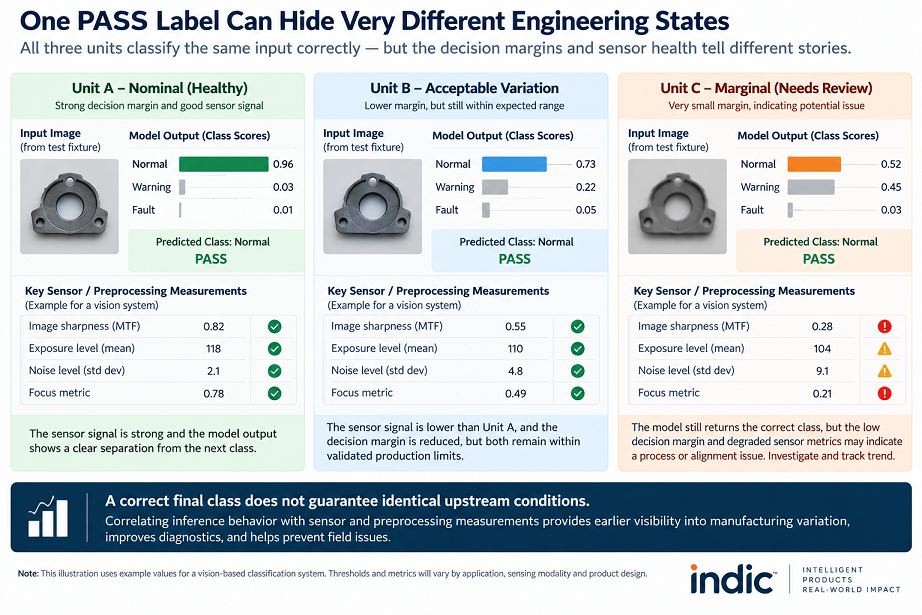
Consider two outputs from a three-class classifier. Unit A returns Normal 0.91, Warning 0.07, Fault 0.02. Unit B returns Normal 0.52, Warning 0.45, Fault 0.03. Both units return Normal, but they do not occupy the same place in the model’s decision space.

The second output sits much closer to a competing class. That alone does not prove Unit B is defective. The difference could arise from legitimate sensor tolerance, fixture variation, preprocessing or the model itself. But recording only “Normal — PASS” throws away potentially useful information.

Comparison of three illustrative Edge AI vision units that all return the correct Normal class but have progressively smaller first-versus-second class margins and shifted upstream measurements. The shown sharpness, luminance, image-noise and focus values are explicitly illustrative and are not production acceptance limits.
A correct final class can coexist with different decision margins and upstream sensor conditions. Correlating validated upstream measurements with model behavior can expose process movement that a class-only PASS/FAIL record may miss.

When validated appropriately, characteristics such as class separation, output-vector position or repeatability can be useful production observables. Their role does not always need to be immediate rejection. Some may be more valuable as process indicators.

Some Measurements Should Reject Units. Others Should Monitor the Process.

A robust production-test plan usually needs more than one kind of limit.

Hard acceptance rules

These identify unambiguous nonconformities such as wrong firmware, missing model, invalid model hash, failed memory, failed sensor communication, missing calibration record or provisioning failure.

Bounded engineering measurements

These are continuous physical or signal-path characteristics such as supply current, sensor offset, calibration residual, signal amplitude, image-quality measure or timing error. Limits should come from validated engineering requirements and the measurement system—not from convenient round numbers. Where measurement uncertainty is significant, the relationship between specification limits and test acceptance limits also matters. NIST's conformity-assessment guidance explains how decision rules and guard bands affect the competing risks of accepting nonconforming product and rejecting conforming product.

Inference-specific acceptance rules

These evaluate intelligent behavior and may involve correct class plus a validated separation condition, localization error, regression error, anomaly-score region or output-vector criteria.

Statistical process indicators

These are measurements worth recording because their movement can expose manufacturing or fixture drift before an individual unit necessarily violates the product specification. A declining classification margin across successive production lots, for example, might correlate with optical alignment movement, sensor-lot differences, fixture illumination drift, calibration change, preprocessing change or assembly-process movement.

It would be poor engineering to reject units solely because an unvalidated trend metric moved. It would also be poor engineering to discard the information. That distinction—unit acceptance versus process monitoring—is one of the most important decisions in intelligent-device production test.

Do Not Turn a Golden Unit Into the Product Specification

Golden or reference units remain useful. They can verify fixture health, detect obvious changes in test setup and provide a stable reference for line setup. But an Edge AI acceptance specification should not quietly become: every unit must behave exactly like this unit.

The reference unit has its own component tolerances, sensor behavior, alignment and calibration state. The production specification should come from the validated product definition and appropriate population evidence. The golden unit is evidence about the test system; it is not automatically the definition of a conforming product population.

Avoid Building the Fixture Around a Decision-Boundary Sample

A tempting way to make an AI production test appear rigorous is to choose a difficult sample that the model barely classifies correctly. That can produce a fragile manufacturing test.

If the stimulus intentionally lies close to the model’s decision boundary, small and otherwise acceptable changes in fixture position, sensor noise or product tolerance can dominate the result. The station then becomes extremely sensitive without necessarily becoming better at finding meaningful manufacturing defects.

For 100% production testing, use controlled stimuli with enough margin to expose the relevant hardware, sensor, calibration and execution failures without excessive sensitivity to irrelevant variation. For engineering validation and process audits, difficult examples and corner conditions can be used to characterize how product variation affects model decision boundaries. The two activities serve different purposes.

Bridging the Gap: Structuring Edge AI Test Strategy Across NPI Gates

Production-test criteria for an intelligent device are easier to defend when the evidence behind them is built progressively rather than defined only when the product reaches end-of-line testing.

EVT, DVT and PVT terminology varies somewhat among hardware organizations, but the underlying maturity progression is familiar: early builds establish whether the production-intent design works and expose failure mechanisms; later builds validate a production-worthy configuration; and production-validation builds demonstrate that the manufacturing and test processes can reproduce that configuration under production conditions. Instrumental's overview of EVT, DVT and PVT stage gates describes this progression while also noting that individual companies may use the terms differently.

For an Edge AI product, this progression creates an important opportunity: mature the test architecture alongside the product rather than attempting to define inference acceptance criteria only when the end-of-line station is being finalized.

The allocation below is a practical engineering synthesis, not a universal EVT/DVT/PVT standard:

NPI build stage Primary Edge AI test objective Test and acceptance focus
EVT
Engineering Validation
Establish observability, baseline behavior and fault-isolation capability.
  • Validate a known-digital-input or replay path where the architecture supports one.
  • Characterize sensor, optical, analog-front-end and preprocessing behavior under controlled conditions.
  • Determine which upstream measurements correlate meaningfully with inference behavior.
  • Identify which configuration, calibration and runtime states must be observable for later production diagnosis.
DVT
Design Validation
Control the production-intent intelligent configuration and establish candidate acceptance rules.
  • Version and control the model, quantization, preprocessing, runtime and firmware elements that can affect inference behavior. Framework guidance such as PyTorch's reproducibility documentation illustrates why software, runtime and execution configuration matter when repeatability is being characterized.
  • Establish bounded sensor and signal-path criteria across the operating conditions relevant to the product.
  • Where measurement uncertainty is significant, define acceptance rules with appropriate consideration of guard bands and decision risk, consistent with NIST guidance on conformity decision rules and guard bands.
  • Verify that fixtures and measurement stations have sufficient repeatability and reproducibility to distinguish product variation from measurement-system variation. NIST/SEMATECH measurement-process guidance provides established methods for evaluating repeatability, reproducibility and stability.
PVT
Production Validation
Validate the production test process, traceability and monitoring strategy under line conditions.
  • Verify serial-linked capture of the hardware, firmware, model, calibration and test configuration needed to reconstruct the state of a tested unit. Indic's guide to production test and traceability describes the adjacent manufacturing practice of linking test results, firmware/checksum information and MES records to individual units.
  • Confirm that physical-stimulus tests, digital replay and diagnostic checks behave consistently on the intended production equipment.
  • Validate the end-of-line sequence and cycle time without removing measurements required for meaningful fault isolation.
  • Establish statistical process indicators only where engineering evidence shows that the metric is useful for detecting process movement. NIST AI RMF measurement guidance similarly recommends comparing production behavior with pre-deployment measurements and monitoring changes in system behavior over time.

EVT: Establish What Can Be Observed and Isolated

At EVT, the objective is not to invent the final factory confidence threshold. It is to establish what the engineering team can observe, control and separate.

A replay input that bypasses the physical sensor, for example, is substantially easier to design while the product architecture is still flexible than after interfaces, firmware and diagnostic access have been frozen. The same is true for exposing calibration state, preprocessing statistics or other intermediate measurements that may later be needed to distinguish a sensor-path problem from an inference-path problem.

DVT: Turn Characterization Into Controlled Acceptance Evidence

By DVT, the intelligent-function stack should be treated as a controlled production-intent configuration. If model weights, quantization, preprocessing, runtime behavior or firmware change after acceptance behavior has been characterized, the affected validation evidence should be reconsidered rather than assuming that previously established limits remain valid.

DVT is also where the quality of the measurement system becomes increasingly important. A production limit is useful only if the fixture and measurement process can resolve the characteristic being controlled. Station-to-station variation, setup variation and longer-term measurement drift should therefore be distinguished from real product variation before limits are carried forward into production.

PVT: Prove the Test Process Works as a Manufacturing Process

By PVT, the question shifts from whether an engineering test can be performed to whether the manufacturing system can perform it consistently and traceably.

Can the line reproduce the intended stimulus and measurement conditions? Can a failed unit be traced to the hardware, firmware, model and calibration state under which it was tested? Can the test sequence operate within the required production cycle time without discarding evidence needed for diagnosis?

Some inference-derived measurements may also become useful process indicators at this stage. A class margin, anomaly score or other model output can be trended when validation has shown that movement in the metric correlates with a meaningful product or process condition. It should not become an individual-unit reject criterion merely because it is convenient to collect.

For an Edge AI product, the purpose of developing the test strategy through NPI is to build the evidence required for production acceptance before the production line is asked to make the final PASS/FAIL decision.

Illustrative Engineering Scenario: The Product Still Passes While the Process Moves

Consider a compact embedded vision product using a camera, fixed lens, embedded processor and classification model. At end-of-line, the fixture presents a controlled reference target. The initial acceptance criterion is simple: does the product classify the target correctly? Every unit continues to pass.

Over time, however, the mechanical position of the lens assembly begins to shift. The model is tolerant enough that the expected class remains the winner. If production records only the final class, nothing appears to have changed.

Now suppose the tester also records a validated image-sharpness measure, first-versus-second-class separation, calibration status and final class. A trend may become visible:

Mechanical change → image-quality change → input representation shifts → decision margin narrows

That sequence does not prove that a field failure will occur. It does reveal a manufacturing change that the binary model decision did not expose. The correct response is not automatically to increase the AI threshold or reject every unit. The engineering question becomes: why is the optical path moving, and is that movement still inside the validated product envelope?

This is an illustrative engineering scenario, not an Indic customer case or measured Indic production result.

Production Traceability Has to Include the Intelligent Configuration

Traditional electronics traceability commonly records hardware and firmware configuration. An intelligent product may require a broader configuration record because behavior can depend on the model file or model hash, weights, quantization, preprocessing parameters, runtime, label mapping, calibration constants, firmware and hardware revision.

Two physically identical units need not behave identically if their executable inference configuration differs. Production therefore needs enough configuration identity to reconstruct which intelligent-function stack was installed when the unit was tested.

  • Unit serial or lot
  • Hardware revision
  • Firmware / bootloader revision
  • Model identifier or hash
  • Runtime or accelerator-stack revision
  • Calibration revision
  • Fixture or station identifier
  • Stimulus/reference identifier
  • Selected sensor or preprocessing metrics
  • Inference result and selected inference observables
  • Test-rule revision
  • Final disposition

Not every raw frame or waveform needs to be stored. The objective is to retain enough evidence to distinguish later among product variation, configuration change, fixture drift and manufacturing-process movement. For conventional context, Indic’s published guide to production test and traceability describes serial-linked FCT/EOL results, firmware/checksum control and MES traceability. Those are adjacent production-test practices; this article does not claim they are evidence of a specific Edge AI customer implementation.

Design for Test Cannot Be an Afterthought

The production-test problem ultimately becomes an architecture problem. If the final product cannot expose useful sensor measurements, retrieve preprocessing diagnostics, accept an appropriate controlled digital input, identify the deployed model, identify the runtime, verify calibration state or record useful inference metrics, a production fixture cannot easily recover that observability after the design is frozen.

An Edge AI DFT review should therefore treat observability and injection as product requirements where they materially improve diagnosis. Indic’s Design for Test material similarly emphasizes adding test points, access to critical nodes and diagnostic features during design rather than after manufacturing begins.

  • Can the sensor path and digital inference path be isolated?
  • Can a known digital input be injected at a useful point?
  • Can the relevant intermediate measurements be observed?
  • Can model, runtime and calibration identity be reconstructed?
  • Can a failing unit point engineering toward a likely subsystem rather than simply reporting “AI FAIL”?

Testability is not solely a fixture-design activity. Some of the most valuable production-test capabilities have to be designed into the product.

The Production Acceptance Matrix

The overall method can be summarized as an allocation problem. For every important characteristic in the sensor-to-decision chain, decide which acceptance method actually fits it.

Characteristic Best-fit method Example
Configuration identity Exact Firmware/model hash
Physical characteristic Bounded Supply current, sensor offset
Signal quality Bounded / trended Validated image or acoustic quality metric
Controlled digital inference Exact or bounded Validated replay result
Intelligent behavior Inference-specific Class margin, localization error
Manufacturing movement Statistical Lot-to-lot shift in selected metrics

This is not a new law of AI testing. It is a practical way to prevent every observable from being collapsed into one inappropriate confidence threshold. The production engineer’s job is not to make an intelligent device behave like a conventional resistor. It is to make the evidence supporting product conformity explicit.

The Real Goal: Deterministic Acceptance, Not Artificially Identical AI Outputs

Production quality does not require every model score to be the same. It requires a test architecture in which the reason a unit passes or fails is controlled and understandable.

Correct hardware and configuration → healthy sensor path → controlled digital execution → validated intelligent behavior → correct application decision

Some evidence in that chain is exact. Some is bounded. Some is model-specific. Some is statistical. What should not be ambiguous is the rule that turns that evidence into a manufacturing decision.

Probabilistic inference does not require probabilistic production quality. It requires a better-defined acceptance architecture.

Edge AI Production-Test Architecture Worksheet

The Edge AI Production-Test Architecture Worksheet turns the article’s reasoning into a working engineering planning tool. It helps teams map the sensor-to-decision chain, identify missing observability and injection points, assign exact, bounded, inference-specific or statistical test methods, plan known-input replay, define physical-fixture controls, specify production traceability and conduct a readiness review.

Request the Edge AI Production-Test Architecture Worksheet. Use the Indic contact form and mention “Edge AI Production-Test Architecture Worksheet” in the message field.

For additional context on Indic’s current test solutioning and automation capabilities, see Technical Expertise.

Selected Technical Sources

Indic Edge AI Production Test Architecture Worksheet
Indic-Edge-AI-Production-Test-Architecture-Worksheet
Close
After signing up the PDF will be emailed to you at the address you provide.  Please use a company address - gmail, yahoo, outlook, etc. will not be accepted.
Thank you! Your submission has been received!
Oops! Something went wrong while submitting the form.
Join us to stay updated with our latest blog updates, manufacturing and assembly trends, news and announcements!
Thank you! Your submission has been received!
Oops! Something went wrong while submitting the form.