Why Edge AI Hardware Can Fail During Scale-Up

5

min read

Why Edge AI Hardware Can Fail During Scale-Up Even After Passing Lab Validation

An Edge AI product can pass lab validation and still fail to meet its performance or conformance requirements during scale-up because the lab normally proves a limited number of known system states under defined conditions. Production introduces a physical population, a broader operating envelope and multiple approved configuration states. Production readiness therefore requires evidence that required end-to-end behavior remains within specification across the combinations that matter to the product.

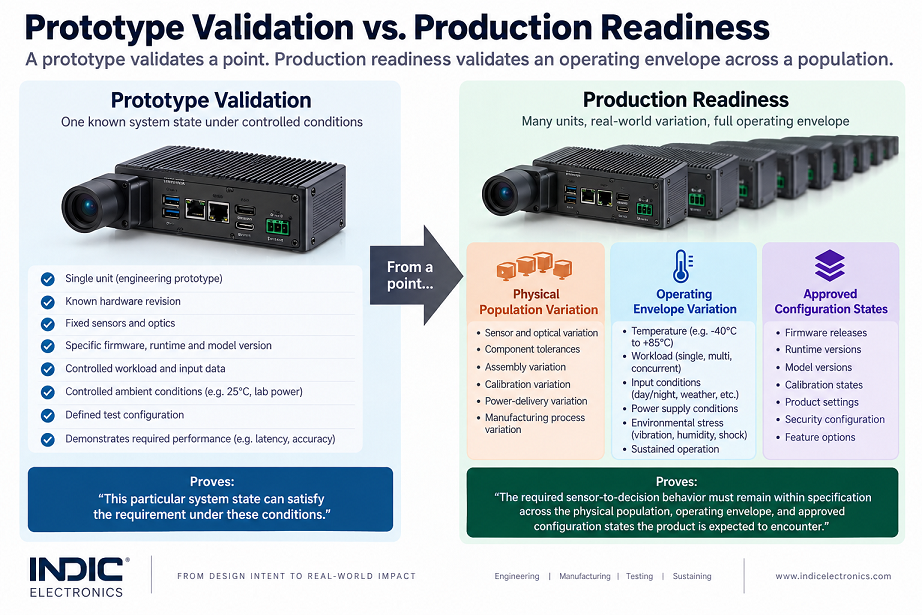
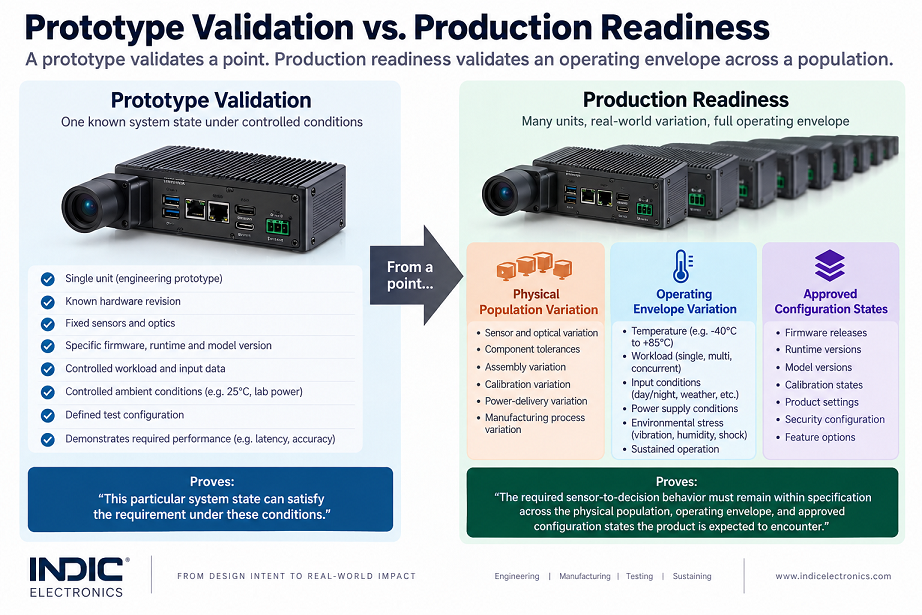
A prototype validates a point. Production readiness validates an operating envelope across a population.

That statement needs an important qualification.

Not everything that changes between prototype and production is the same kind of variation.

Component tolerances, sensor characteristics, optical alignment, assembly conditions and some calibration effects are forms of physical population variation. Temperature, workload, power conditions and environmental stress are part of the operating envelope. Firmware, runtime, model and product configurations are normally controlled discrete states.

All three can influence product behavior, but they should not be collapsed into one statistical concept.

The engineering question before scale-up is therefore not simply:

Did the prototype pass?

It is:

Which physical variations, operating conditions or allowed system states can move an important product requirement, what mechanism produces that movement, what evidence exposes it, and at which lifecycle gate should that evidence be generated?

That last question - where should the evidence be generated? - is central.

Production readiness is not one enormous end-of-line test. Some evidence belongs in DVT. Some belongs in qualification. Some belongs in PVT. Some controls should run on every production unit. Others may belong in periodic production audit or field monitoring.

The engineering task is to allocate the right evidence to the right gate.

Prototype validation compared with production readiness for Edge AI hardware, showing one known engineering system state versus production-relevant physical population variation, the required operating envelope, and approved configuration states.
Figure 1. Prototype validation demonstrates that a known Edge AI system state can meet its requirements under defined conditions. Production readiness requires evidence that acceptable sensor-to-decision behavior persists across expected unit variation, operating conditions, and approved configuration states.

What Does a Lab Validation Pass Actually Prove?

When an engineering team validates an Edge AI prototype, it usually knows - or can reconstruct - a reasonably specific system state.

That state may include:

  • hardware revision;
  • sensor and optical configuration;
  • firmware;
  • operating system or BSP;
  • AI runtime and libraries;
  • model version;
  • calibration;
  • preprocessing configuration;
  • power mode;
  • cooling arrangement;
  • workload;
  • input stimulus;
  • ambient conditions.

If that configuration satisfies a latency, task-performance or functional requirement, the result is valuable.

It establishes:

This system state can satisfy the requirement under these conditions.

Scale-up asks something broader:

Can acceptable behavior survive the range of physical units, operating conditions and approved configurations that the production product may legitimately encounter?

This distinction matters because engineering evidence has meaning only in relation to the conditions under which it was produced.

MLPerf Inference makes that principle explicit in a benchmarking context. Its Edge benchmark defines scenarios, request patterns and associated metrics rather than treating inference performance as a single context-free number. MLCommons also records the software stack and system associated with a result.

That does not make MLPerf a production-validation method.

It illustrates a more general engineering rule:

A performance result is meaningful only when the system, workload, operating condition and metric are defined.

A prototype pass therefore provides important evidence.

It does not automatically establish the behavior of the future production population.

Sensor and Optical-Path Variation Can Change the Data Presented to the AI Function

In a vision-based Edge AI product, the model does not observe the physical scene directly.

The information path is closer to:

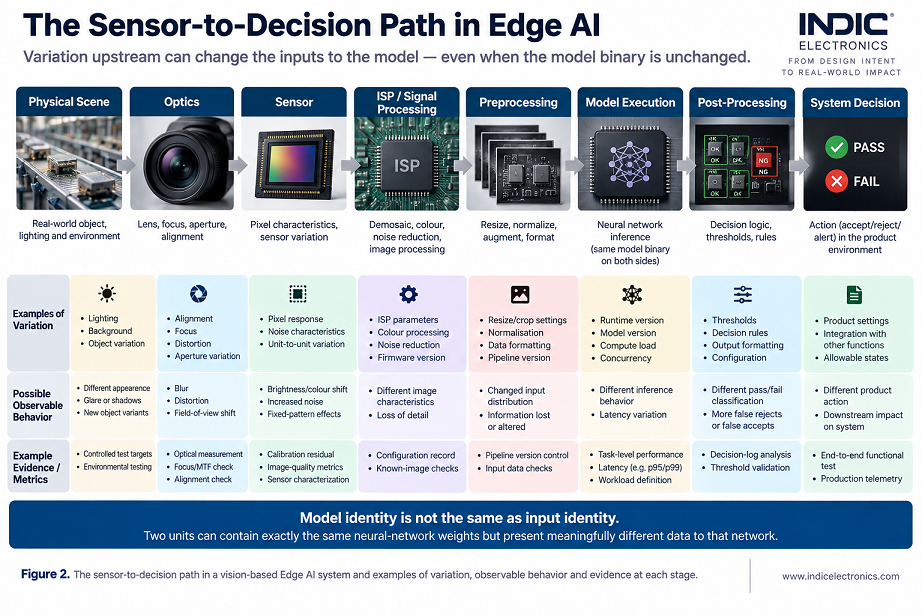
Physical Scene -> Optics -> Sensor -> ISP / Signal Processing -> Preprocessing -> Model Execution -> Post-Processing -> System Decision

Sensor-to-decision path for a vision-based Edge AI product, showing variation, observable behavior and example evidence across the physical scene, optics, sensor, ISP, preprocessing, model execution, post-processing and final system decision.
Figure 2. Sensor-to-decision path in a vision-based Edge AI system. Variation introduced before or during inference can change model inputs, timing or downstream decision behavior even when the model binary itself is unchanged.

Variation introduced upstream can alter the information presented to the model even when the neural-network weights themselves are unchanged.

Depending on the product, relevant factors may include:

  • optical alignment;
  • focal characteristics;
  • distortion;
  • sensor response;
  • calibration;
  • ISP configuration;
  • mechanical displacement;
  • preprocessing.

The important distinction is:

Model identity is not the same as input identity.

Two units can contain the same model binary while presenting different representations of the physical world to that model.

Camera-aware neural-network research provides a useful example of this principle. The CAM-Convs work at CVPR 2019 showed, for the single-view depth-estimation task studied, that a network trained using images from one camera model generalized poorly to imagery from a different camera model, and that explicitly accounting for camera parameters improved cross-camera generalization.

That evidence should not be stretched into the claim:

Camera manufacturing variation causes Edge AI failure.

That would be too broad.

The defensible conclusion is narrower:

Where task behavior is sensitive to the sensor, optical or calibration characteristics that determine model input, those characteristics belong inside the product-validation argument.

The causal path becomes:

sensor / optical / calibration change -> changed input representation -> possible change in task behavior -> product requirement evaluated

Useful evidence depends on the product and failure mechanism. It might include:

  • calibration residual;
  • known-target response;
  • image-quality measurement;
  • controlled task-level test;
  • another product-specific discriminating metric.

There is no universal test.

The measurement should be selected because it exposes the mechanism that can move the product requirement.

Engineering Check for PVT

If apparently equivalent units communicate correctly and inference executes, but task behavior varies between units, ask whether manufacturing control proves only sensor availability or also the optical/calibration characteristics that materially affect the AI input.

Compute Performance Is a System Behavior, Not an Accelerator Specification

A second scale-up assumption is:

The accelerator met the target in development, so the production system has adequate inference performance.

That may be true.

But it has not been proven merely by establishing accelerator capability.

End-to-end product timing can also depend on:

  • preprocessing;
  • memory traffic;
  • CPU activity;
  • accelerator utilization;
  • scheduling;
  • I/O;
  • concurrent workloads;
  • post-processing;
  • power state;
  • thermal state.

For many real-time products, average latency is not enough.

A system may meet its average latency requirement while occasionally missing a deadline because of tail behavior.

MLPerf's use of defined scenarios and metrics illustrates why workload context matters. A benchmark result is associated with a system and software stack and is generated under defined load rules rather than treated as a universal property of the accelerator.

The production lesson is not:

Use MLPerf as your PVT test.

It is:

A meaningful performance claim needs a defined complete system, workload, operating condition, duration and metric.

Before release, useful questions therefore include:

  • What exact workload produced the passing result?
  • What other processing was active?
  • Was this a short burst or sustained operation?
  • Is average latency the real product metric?
  • Does tail latency or deadline-miss rate matter?
  • Which firmware and runtime configuration was used?
  • Which power state was active?
  • At what thermal condition was the measurement taken?

That shifts the engineering question from:

Did the accelerator benchmark pass?

to:

Did the complete product maintain the required behavior across the workload conditions that matter to the application?

Thermal and Power Conditions Can Produce a Performance Failure Without a Functional Crash

An Edge AI product does not have to stop working to fail its requirement.

It can remain operational while becoming too slow.

Modern compute platforms use thermal and power-control mechanisms to keep silicon and system operation inside electrical and thermal limits.

NVIDIA's Jetson Thor power and thermal-management documentation provides a concrete example. It describes thermal zones, trip points and a feedback governor in which increasing temperature can select progressively stronger cooling states. Those states reduce allowable CPU and GPU clock frequencies. NVIDIA explicitly notes that software clock throttling directly affects performance.

For that platform, a defensible causal chain is:

temperature rises -> thermal-control feedback selects stronger cooling state -> CPU/GPU frequency caps decrease -> available execution performance decreases -> inference latency or throughput may move outside the product requirement

The finished product can encounter a different thermal condition from the development setup because it may have:

  • a sealed or constrained enclosure;
  • neighboring heat sources;
  • different airflow;
  • final thermal-interface materials;
  • sustained AI workloads;
  • simultaneous subsystem activity;
  • different ambient conditions.

The AI model has not changed.

The environment in which it executes has.

Power delivery can produce another path.

NVIDIA also documents hardware clock throttling in response to current/power limits and fast transient conditions such as overcurrent or voltage drop at the PMIC.

For that implementation:

power-delivery transient -> current or voltage-limit event -> hardware clock throttling -> reduced available compute performance -> product timing requirement may be at risk

This is a platform-specific example, not a claim that every Edge AI processor behaves identically.

The broader product-development lesson is:

When a platform can dynamically alter available compute performance in response to thermal or electrical state, sustained system validation must observe those states rather than treating compute capability as fixed.

Useful evidence may include:

  • temperature;
  • clock state;
  • current or power behavior;
  • workload state;
  • sustained latency;
  • throughput;
  • throttling indicators.

No universal temperature or latency threshold should be invented.

Those limits belong to the product requirement and architecture.

Engineering Check for Sustained Performance

If tail latency grows under sustained operation, correlate timing with temperature + clock state + workload + power behavior before assuming the regression is necessarily in the model or runtime.

For broader environmental validation, Indic already describes environmental stress and screening work involving temperature variation, humidity, vibration and shock. That is relevant adjacent engineering capability; it should not be represented as evidence of prior Edge AI deployments.

Intelligent-Device Identity Can Extend Beyond the BOM

Traditional manufacturing genealogy asks:

What physical product did we build?

Depending on risk and process, that may involve:

  • serial number;
  • component or lot information;
  • assembly history;
  • process history;
  • test results.

IPC-1782B establishes minimum manufacturing and supply-chain traceability requirements based on perceived risk for electronic products, processes, assemblies, parts and components.

But IPC-1782B does not prescribe:

  • AI model hashes;
  • Edge AI MLOps;
  • runtime genealogy;
  • model-release management.

Those should not be attributed to the standard.

Intelligent hardware adds a separate systems-engineering question:

What information must be reconstructable later to determine the behavioral state of an affected unit or production population?

Depending on architecture, that may involve:

  • firmware;
  • BSP or operating-system build;
  • inference runtime;
  • model version;
  • preprocessing configuration;
  • calibration;
  • product settings.

The correct granularity is architecture-dependent.

For example:

  • calibration may be unique to a unit;
  • firmware may correspond to a production release;
  • runtime may be controlled at product-build level;
  • model version may be fleet-controlled;
  • configuration may vary by product variant.

That does not imply every item must always be stored independently against every serial number.

The useful principle is:

If a hardware or configuration state can materially influence product behavior or root-cause analysis, the organization should know how that state is controlled and how it can be reconstructed for the relevant unit or population.

This is where manufacturing genealogy and intelligent-device configuration management begin to overlap.

Indic already documents adjacent production test and traceability practices in which firmware version/checksum is associated with unit serial in MES and ICT/FCT/EOL results write to the same record.

That does not establish direct Edge AI production experience.

It does demonstrate an underlying production-control discipline relevant to more complex intelligent-device genealogy.

A Functional Pass Is Not Automatically Proof of Intelligent-Function Conformance

Terms such as ICT, FCT and EOL describe categories of production test.

They do not, by themselves, define the failure mechanisms each station covers.

Indic's published DFT and ICT/JTAG/FCT/EOL coverage planning already makes this distinction in conventional electronics by allocating coverage across ICT, boundary-scan JTAG, FCT and EOL through a coverage matrix.

A production station might establish that:

  • power rails are present;
  • interconnects are correct;
  • interfaces communicate;
  • the sensor responds;
  • firmware loads;
  • inference executes;
  • an output is generated.

But another question may remain:

Does the complete intelligent function meet the product requirement under the conditions allocated to this verification stage?

Possible gaps could involve:

  • calibration sensitivity;
  • controlled input-path variation;
  • sustained thermal behavior;
  • workload-dependent tail latency;
  • configuration mismatch.

It would be equally wrong to conclude:

FCT cannot test these things.

A properly engineered FCT or EOL station can include:

  • controlled stimuli;
  • calibration procedures;
  • realistic sensor stimulation;
  • latency measurements;
  • task-level checks;
  • thermal-state checks;
  • product-specific extended workloads.

The issue is therefore not the station's label.

It is coverage.

Assembly Integrity

Was the hardware assembled correctly?

Functional Conformance

Do the required hardware and software functions operate?

Intelligent-Function Conformance

Does the complete sensor-to-decision system satisfy the product behavior allocated to this verification stage?

And importantly:

Not every product requirement needs to be retested on every production unit.

Some relationships should be established in DVT or qualification.

Some should be demonstrated for manufacturing reproducibility during PVT.

Only the appropriate controls need to become unit-level production tests.

Production Readiness Is an Evidence-Allocation Problem

Listing scale-up risks is not enough.

The useful question is what the engineering team does with them.

For every significant product requirement, the team should be able to answer:

  1. What variation or allowed state can move the requirement?
  2. Through what mechanism?
  3. What observable behavior changes?
  4. What evidence discriminates the change?
  5. At which lifecycle stage should that evidence be generated?
  6. What acceptance criterion or control follows?
  7. What provenance will be required later?

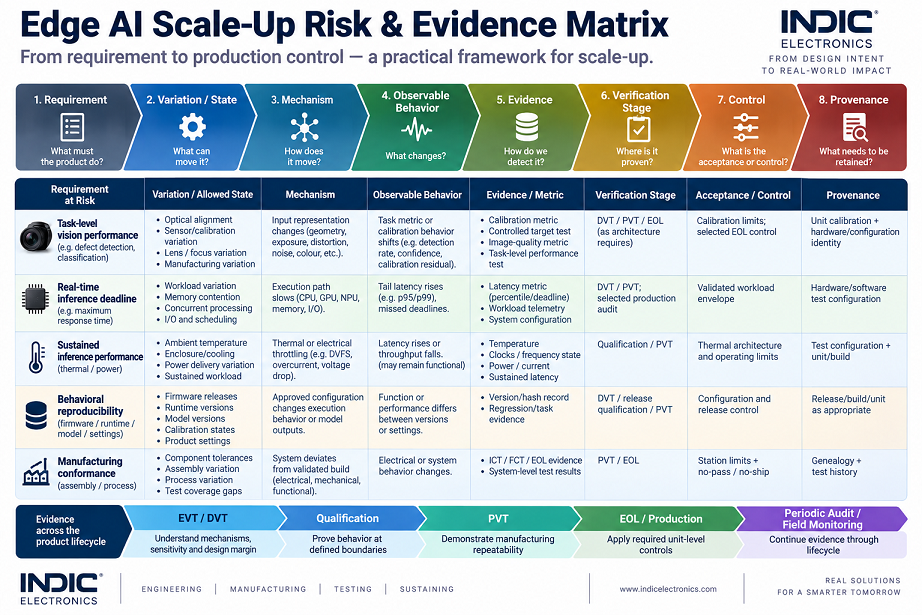
A practical engineering synthesis is the Edge AI Scale-Up Risk & Evidence Matrix:

Requirement at RiskVariation / Allowed StateMechanismObservable BehaviorEvidence / MetricVerification StageAcceptance / ControlProvenance
Product-specific requirementWhat changes or is permitted to change?How does it affect behavior?What becomes observable?What measurement reveals it?Where should proof be generated?What keeps the product inside the validated envelope?What must be reconstructable later?
Edge AI Scale-Up Risk and Evidence Matrix linking product requirements to variation or allowed states, mechanisms, observable behavior, evidence, verification stages, acceptance controls and provenance across EVT/DVT, qualification, PVT, production and field monitoring.
Figure 3. Edge AI Scale-Up Risk & Evidence Matrix. The framework connects each product requirement to the variation or configuration state that can affect it, the mechanism and observable behavior, the evidence required, where that evidence should be generated, and the control and provenance needed for production readiness.

The sequence is:

Requirement -> Variation or State -> Mechanism -> Observable Behavior -> Evidence -> Verification Stage -> Acceptance / Control -> Provenance

The value lies in the relationship among the columns.

This is not a replacement for:

  • DFMEA;
  • PFMEA;
  • qualification planning;
  • DFT;
  • reliability engineering;
  • regulatory testing;
  • safety engineering.

It addresses another question:

Where will the evidence proving that a known Edge AI scale-up risk is controlled actually come from?

A common readiness gap is not failure to recognize the risk.

It is recognizing the risk without assigning the evidence that proves it has been contained.

Worked Example: A Vision-Based Inspection Device

Consider an illustrative industrial inspection product.

This is an engineering example, not an Indic customer case.

The product uses a camera and local inference to identify defects on items moving through a production line.

Two different mechanisms threaten two different requirements.

Failure Path A - Sensor / Calibration

Requirement at risk: Defect-detection performance.

Scale-up variation: Camera alignment or calibration differs from the validated engineering configuration.

Mechanism: Acquisition geometry or image characteristics presented to the AI pipeline change.

Observable behavior: Calibration quantities move or controlled task-level results change.

Possible evidence: Depending on product design:

  • calibration residual;
  • known-target image measurement;
  • controlled task-performance test.

Where should that evidence live?

DVT - characterize sensitivity and establish the acceptable sensor/calibration envelope.

PVT - demonstrate that the production process repeatedly produces units within that envelope.

EOL - where justified by risk and test-time constraints, measure the unit-specific calibration quantity or another representative discriminating condition.

Provenance - retain the calibration and hardware/configuration identity needed for later root-cause analysis.

Notice what is not required.

Every production unit does not need to repeat the complete AI qualification program.

DVT and PVT establish the engineering relationship.

Production applies the minimum appropriate control required to keep units inside the validated space.

Failure Path B - Thermal / Compute

The same device has a maximum response-time requirement.

Requirement at risk: Maximum inference-response time.

Scale-up condition: The final enclosure and sustained workload produce more demanding thermal conditions than the development setup.

Mechanism: On a platform with thermal frequency management, increasing temperature can reduce allowable compute frequency; electrical-limit events may also trigger throttling.

Observable behavior: Tail inference latency increases.

Evidence: Correlate:

  • workload;
  • temperature;
  • compute-clock state;
  • power behavior;
  • inference latency.

Where should that evidence live?

DVT / Qualification - establish sustained timing behavior across required thermal and workload conditions.

PVT - verify that the final production build, cooling path, mechanical assembly and manufacturing process reproduce the validated thermal behavior.

EOL - normally do not repeat hours of environmental qualification on every unit. Instead test the production characteristics that DVT/PVT demonstrated matter to the requirement.

Those might include, depending on design:

  • cooling-path assembly;
  • interface integrity;
  • power behavior;
  • fan operation;
  • another discriminating unit-level control.

If timing cannot remain inside specification, the engineering response could involve:

  • thermal architecture;
  • workload scheduling;
  • power mode;
  • compute platform;
  • system partitioning;
  • timing requirement.

This is what a useful scale-up evidence plan should do:

Connect the product requirement to the mechanism, the evidence, the verification stage and the appropriate production control.

Where Should Different Production-Readiness Evidence Live?

Lifecycle StagePrimary Engineering Question
EVT / DVTWhat can cause the important system requirement to move?
QualificationDoes required behavior remain acceptable at defined environmental, thermal, mechanical or electrical boundaries?
PVTCan the actual manufacturing process repeatedly reproduce the validated product and required controls?
EOL / Production TestWhat must be proven on each unit before shipment?
Periodic Production AuditWhat should be sampled periodically rather than tested on every unit?
Field MonitoringWhat evidence should continue after release to detect drift, configuration problems or operating conditions not exposed earlier?

This leads to the central engineering conclusion:

Production readiness is not one test. It is an evidence architecture distributed across the product lifecycle.

Six Questions to Ask Before Authorizing Scale-Up

1. What exactly did lab validation prove?

Which hardware, software, model, calibration, workload and environmental state produced the passing result?

2. What changes across the production population?

Which sensor, component, assembly, calibration or process variations can materially influence the product requirement?

3. What operating envelope matters?

Which temperature, power, workload, input or environmental conditions have to be covered?

4. Which configuration states are permitted?

Which firmware, runtime, model, calibration or product settings may legitimately exist in production or the field?

5. What evidence proves each important risk is controlled - and where is it generated?

Does proof belong in:

  • DVT;
  • qualification;
  • PVT;
  • EOL;
  • periodic audit;
  • field monitoring?

6. Can the behavioral state be reconstructed later?

Can an outlier or field failure be related to the relevant:

  • hardware/build state;
  • software configuration;
  • model;
  • calibration;
  • production-test history?

If these questions cannot be answered, that does not prove the product will fail.

It means the organization may not yet possess enough evidence to justify confidence that the production population will reproduce the validated behavior.

"Passed Validation" Should Describe an Evidence Architecture

Moving Edge AI hardware from prototype to production is not merely a manufacturing-repeatability problem.

It is a systems-evidence problem.

Traditional industrialization disciplines remain essential:

  • DFT;
  • test coverage;
  • traceability;
  • qualification;
  • process control;
  • configuration management.

Indic already publishes adjacent engineering practices around complementary ICT/JTAG/FCT/EOL coverage, firmware/checksum control, serial-linked MES traceability and environmental screening.

Useful related resources include:

Those disciplines do not establish that Indic has already industrialized customer Edge AI products.

They do show why intelligent-hardware industrialization should not be separated from conventional electronics engineering disciplines.

Edge AI adds another requirement:

Validation, industrialization and production control must collectively provide evidence that required sensor-to-decision behavior remains within specification.

A more useful definition of production readiness is therefore:

An Edge AI product is ready to scale when the engineering team has credible evidence that required end-to-end behavior remains within specification across the physical population, operating envelope and approved configuration states expected in production - and has allocated the necessary evidence and controls to the appropriate validation, qualification, production and lifecycle gates.

A successful prototype remains essential evidence.

It simply is not the whole evidence architecture.

Before You Freeze the PVT Gate

A PVT release should not rely on the assumption that reproducing the prototype automatically reproduces its behavior.

Before release, the team should be able to map each important requirement to:

variation or allowed state -> mechanism -> observable behavior -> evidence -> verification stage -> acceptance/control -> provenance

The Edge AI Production Readiness Evidence Matrix converts that reasoning into a working engineering worksheet for requirement-at-risk definition, variation/configuration identification, failure mechanisms, evidence planning, verification-stage allocation, acceptance criteria, production controls, provenance and unresolved risks.

Do your PVT release gates prove production behavior - or mainly confirm that the prototype baseline was reproduced?

Before You Freeze Your PVT Gate

A PVT release should prove production behavior—not just confirm that a prototype baseline was reproduced. Download the Edge AI Production Readiness Evidence Matrix to map requirements, mechanisms, and verification stages across your product lifecycle.

Request the Evidence Matrix (PDF)

Close
After signing up the PDF will be emailed to you at the address you provide.  Please use a company address - gmail, yahoo, outlook, etc. will not be accepted.
Thank you! Your submission has been received!
Oops! Something went wrong while submitting the form.
Join us to stay updated with our latest blog updates, manufacturing and assembly trends, news and announcements!
Thank you! Your submission has been received!
Oops! Something went wrong while submitting the form.